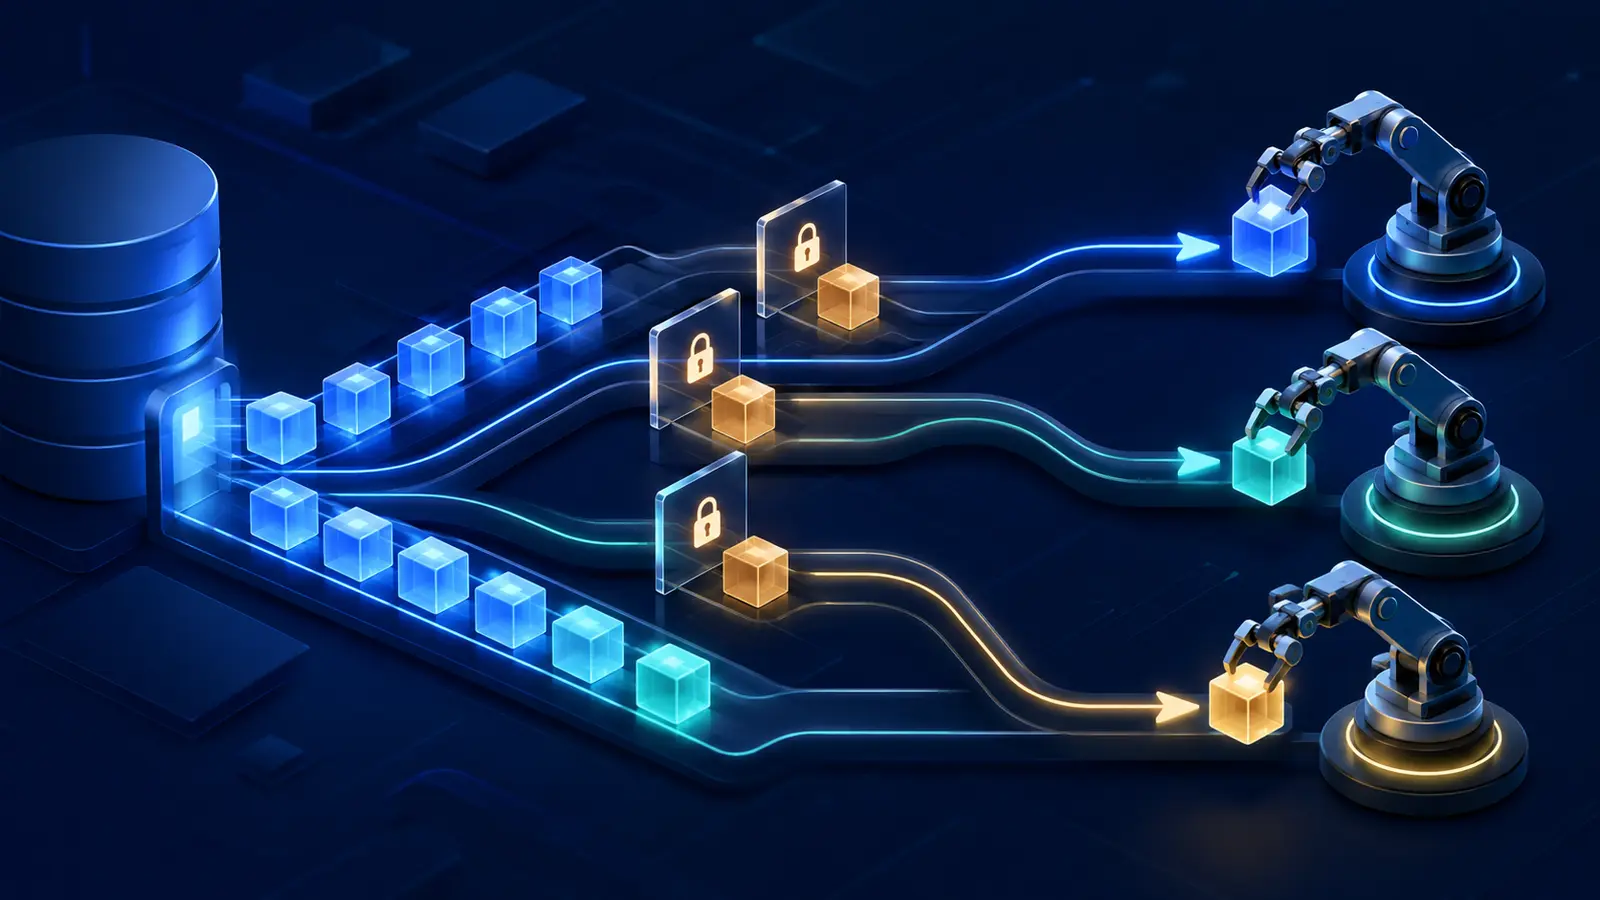
Building a PostgreSQL Job Queue with FOR UPDATE SKIP LOCKED

Many backend systems eventually need work to happen outside the request that created it: send an email, resize a file, refresh a search index, call a partner API, or generate an embedding.
A dedicated queue is often the right tool. But when PostgreSQL is already the system of record and the workload is modest, a database-backed queue can be a useful starting point. The difficult part is not inserting a row. It is allowing several workers to claim jobs concurrently without processing the same available row at the same time or making every worker wait behind one busy row.
PostgreSQL provides a building block for that problem: FOR UPDATE SKIP LOCKED.
This article develops a practical design around it. The focus is not only the claim query, but also the transaction boundary, crash recovery, retries, idempotency, indexing, and the limits of the pattern.
The SQL and behavior in this article were checked against PostgreSQL 18, the current supported major version on August 8, 2026. PostgreSQL 19 was still in beta on that date. Verify details against the documentation for the major version you operate.
The concurrency problem in one query
Imagine two workers running this query at nearly the same time:
SELECT id, payload
FROM jobs
WHERE status = 'pending'
ORDER BY run_at, id
LIMIT 1;
Both can observe the same pending row. A later UPDATE does not retroactively make that earlier selection exclusive. Splitting selection and claiming into unrelated statements therefore leaves a race unless the application adds another coordination mechanism.
FOR UPDATE changes the selection into a locking read. PostgreSQL locks the selected rows against concurrent updates and conflicting row-lock requests until the transaction ends. PostgreSQL 18 documents the row-level behavior and lock lifetime.
With plain FOR UPDATE, another worker that reaches the same first row waits. That protects correctness, but it can serialize consumers behind the oldest job.
SKIP LOCKED changes the waiting behavior. If a selected row cannot be locked immediately, PostgreSQL skips it and continues looking. The PostgreSQL documentation explicitly identifies multiple consumers of a queue-like table as a suitable use case. It also warns that skipping rows produces an inconsistent view, so this is not a general-purpose reporting technique. PostgreSQL 18 documentation: SELECT locking clause
That trade-off is exactly what a worker wants: claim one currently available job, not a globally consistent picture of every job.
Start with a small, explicit schema
Here is a queue table with enough state to demonstrate the lifecycle:
CREATE TABLE jobs (
  id bigint GENERATED ALWAYS AS IDENTITY PRIMARY KEY,
  queue_name text NOT NULL,
  payload jsonb NOT NULL,
  status text NOT NULL DEFAULT 'pending'
    CHECK (status IN ('pending', 'running', 'completed', 'failed')),
  run_at timestamptz NOT NULL DEFAULT now(),
  attempts integer NOT NULL DEFAULT 0,
  max_attempts integer NOT NULL DEFAULT 5,
  locked_at timestamptz,
  locked_by text,
  claim_token text,
  completed_at timestamptz,
  last_error text,
  created_at timestamptz NOT NULL DEFAULT now(),
  CHECK (attempts >= 0),
  CHECK (max_attempts > 0)
);

CREATE INDEX jobs_pending_claim_idx
ON jobs (queue_name, run_at, id)
WHERE status = 'pending';
The partial index contains only pending jobs. Its key order matches an equality condition on queue_name, followed by the due-time range and deterministic id tie-breaker used by the claim query.
For a multicolumn B-tree, PostgreSQL can use equality constraints on leading columns and an inequality on the first following column to limit the scanned index range. PostgreSQL 18 documentation: multicolumn indexes
Partial indexes require care. PostgreSQL must be able to prove at planning time that the query condition implies the index predicate. A literal status = 'pending' matches this predicate, while a parameterized status condition may prevent the planner from using the partial index. PostgreSQL 18 documentation: partial indexes
The index is a starting point, not a promise about a particular plan. Data distribution, queue size, statistics, and requested batch size still matter. Confirm the real query with EXPLAIN (ANALYZE, BUFFERS) on representative data. My guide to reading PostgreSQL query plans covers that workflow.
Claim and transition the job in one statement
The core claim can be expressed as a locking CTE feeding an UPDATE:
BEGIN;

WITH next_job AS (
  SELECT id
  FROM jobs
  WHERE queue_name = $1
    AND status = 'pending'
    AND run_at <= clock_timestamp()
    AND attempts < max_attempts
  ORDER BY run_at, id
  FOR UPDATE SKIP LOCKED
  LIMIT 1
)
UPDATE jobs AS j
SET status = 'running',
    attempts = j.attempts + 1,
    locked_at = clock_timestamp(),
    locked_by = $2,
    claim_token = $3,
    last_error = NULL
FROM next_job
WHERE j.id = next_job.id
RETURNING
  j.id,
  j.payload,
  j.attempts,
  j.max_attempts,
  j.claim_token;

COMMIT;
The application supplies:
$1: the queue name$2: a worker identifier useful for diagnostics$3: a fresh, unguessable claim token generated by the application
The locking clause must be inside the CTE because that is where row selection happens. PostgreSQL notes that a locking clause on the outer query does not automatically apply inside a referenced WITH query. PostgreSQL 18 documentation: locking clauses and WITH
The UPDATE ... RETURNING moves the selected row to running and returns the payload in the same statement. The surrounding transaction should commit immediately after a successful claim.
Why keep this transaction short? Row locks live until transaction end, and PostgreSQL cautions against holding transactions open for long periods. PostgreSQL 18 documentation: explicit locking Long-running transactions can also delay removal of dead row versions that remain potentially visible to them, which adds pressure to vacuum-dependent maintenance. PostgreSQL 18 documentation: routine vacuuming
Do not keep the claim transaction open while making an HTTP call, generating a document, or waiting on another service. Commit the claim, perform the work, then record the outcome in a new transaction.
Why workers do not all claim the same available job
Consider workers A and B:
- Worker A reaches the oldest pending row and obtains its row lock.
- Before A commits, worker B reaches that row.
- Because B uses
SKIP LOCKED, it does not wait for A. It moves to the next lockable row. - Each worker updates and returns the row it locked.
PostgreSQL stops locking once enough rows have been returned to satisfy LIMIT. PostgreSQL 18 documentation: locking with LIMIT With LIMIT 1, each execution is looking for one lockable candidate.
At PostgreSQL's default Read Committed isolation level, each command starts from a snapshot of committed data as of that command's start. Locking and updating commands also account for rows concurrently changed by other transactions according to the documented Read Committed rules. PostgreSQL 18 documentation: Read Committed isolation
The important guarantee is narrow: concurrent claim transactions coordinate access to queue rows. SKIP LOCKED does not create an end-to-end exactly-once processing guarantee.
Commit the result with the claim token
After the external work succeeds, use both the job ID and claim token when recording completion:
UPDATE jobs
SET status = 'completed',
    completed_at = clock_timestamp(),
    locked_at = NULL,
    locked_by = NULL,
    claim_token = NULL
WHERE id = $1
  AND status = 'running'
  AND claim_token = $2
RETURNING id;
Treat a zero-row result as a lost claim, not as success. The job may have been recovered and claimed by another worker.
This guard matters once leases enter the design. A slow worker can outlive its lease, while a recovery process makes the job available again. A fresh claim token distinguishes the current claim from an older worker that wakes up later.
Inference: the token prevents a stale worker from overwriting the database state for a newer claim. It cannot undo an external side effect the stale worker already performed. If the job calls a payment, email, search, or partner API, use an idempotency key or a destination-specific deduplication mechanism wherever the downstream system supports one.
Recover work after a worker disappears
If a process crashes after committing the claim, the row remains running. A queue therefore needs a recovery policy.
One option is a lease. locked_at marks the start of the current claim. A periodic recovery task can return expired work to pending:
WITH expired_jobs AS (
  SELECT id
  FROM jobs
  WHERE status = 'running'
    AND locked_at < $1
    AND attempts < max_attempts
  ORDER BY locked_at, id
  FOR UPDATE SKIP LOCKED
  LIMIT 100
)
UPDATE jobs AS j
SET status = 'pending',
    run_at = clock_timestamp(),
    locked_at = NULL,
    locked_by = NULL,
    claim_token = NULL,
    last_error = 'claim lease expired'
FROM expired_jobs
WHERE j.id = expired_jobs.id
RETURNING j.id;
Here $1 is a cutoff timestamp calculated from the application's lease policy. There is no universal lease duration. It should reflect observed job runtimes, acceptable recovery delay, and whether workers can renew a lease safely.
Jobs that exhausted max_attempts should transition to failed through a separate, explicit path. Keeping that transition separate makes the terminal condition easy to query and alert on.
Inference: a crash can happen after the external effect succeeds but before the completion update commits. A recovered job can then perform the effect again. This design is therefore normally at-least-once from the application's perspective, unless the effect itself is made idempotent or atomically deduplicated.
Retry with a schedule, not a tight loop
When a job fails, record the error and choose either a future retry time or a terminal failure:
UPDATE jobs
SET status = CASE
      WHEN attempts < max_attempts THEN 'pending'
      ELSE 'failed'
    END,
    run_at = CASE
      WHEN attempts < max_attempts THEN $3
      ELSE run_at
    END,
    locked_at = NULL,
    locked_by = NULL,
    claim_token = NULL,
    last_error = $4
WHERE id = $1
  AND status = 'running'
  AND claim_token = $2
RETURNING id, status, run_at, attempts;
The application calculates $3 using its retry policy. Backoff and jitter are application decisions, not properties supplied by SKIP LOCKED.
Do not store secrets or unbounded exception dumps in last_error. A compact error code plus a sanitized message is usually easier to retain and operate safely.
Fairness is approximate
ORDER BY run_at, id gives the claim query deterministic preference among rows it can lock. It does not create strict global FIFO execution.
Inference from the skip behavior: a row held by a slow transaction can be skipped by several later claims, so newer jobs may begin first. A row that is repeatedly locked or repeatedly made eligible can also wait longer than its position suggests.
That is usually acceptable for background work, but it should be an explicit product decision. If strict ordering is a correctness requirement, multiple concurrent workers and SKIP LOCKED may be the wrong model. Consider serial processing per ordering key, partitioned queues, or a broker with the ordering guarantees your use case requires.
Also remember that SKIP LOCKED only changes row-level lock waiting. PostgreSQL still acquires the ordinary table-level lock required by the statement. PostgreSQL 18 documentation: SKIP LOCKED scope
Batch claims carefully
Changing LIMIT 1 to a small batch can reduce database round trips. The same locking behavior applies to the returned rows.
But batch size changes failure and fairness behavior:
- a worker can reserve more work than it can process promptly
- a crash can leave more leases to recover
- one worker can drain most immediately available jobs
- larger updates create more write activity per claim transaction
Start with a small batch, measure, and keep the claim transaction separate from job execution. Do not invent throughput targets from somebody else's system.
This queue is also update-heavy. The earlier article on PostgreSQL HOT updates explains why indexes on frequently changed columns can add write amplification. The partial pending index intentionally includes status in its predicate, so moving a row from pending to running changes index membership. That is useful for claiming, but it is still write work worth including in capacity tests.
Observe queue health, not only lock waits
PostgreSQL exposes current activity and lock information through pg_stat_activity and pg_locks. pg_stat_activity includes wait_event_type and wait_event, and the documentation shows how to inspect active waits. PostgreSQL 18 documentation: monitoring wait events pg_locks can be joined to activity data when investigating blockers. PostgreSQL 18 documentation: pg_locks
For example:
SELECT
  pid,
  application_name,
  state,
  wait_event_type,
  wait_event,
  xact_start,
  query_start
FROM pg_stat_activity
WHERE datname = current_database()
  AND state <> 'idle'
ORDER BY query_start;
Normal SKIP LOCKED contention may not appear as a row-lock wait because the worker skips the locked row instead of waiting. Database wait events are therefore only one part of queue observability.
I would also track application-level signals:
- count of pending, running, completed, and failed jobs by queue
- age of the oldest eligible pending job
- claim-to-completion duration
- retry and terminal-failure counts
- expired-lease recoveries
- jobs approaching
max_attempts - claim queries that return no row while pending jobs exist
The last metric needs interpretation. Pending jobs may be scheduled for the future, locked, or filtered into another queue.
Deadlocks and transaction hygiene still matter
SKIP LOCKED reduces one specific source of queue contention. It does not make the rest of a transaction immune to deadlocks.
If a worker locks a job and then modifies other shared rows in inconsistent order, a cycle can still form. PostgreSQL detects a deadlock and aborts one transaction. The documentation recommends acquiring locks on multiple objects in a consistent order and retrying transactions aborted by deadlock detection when avoidance is not possible. PostgreSQL 18 documentation: deadlocks
The cleanest queue transaction is narrow:
- claim one job
- commit
- perform the work
- record success or retry in a new guarded transaction
That structure keeps database locks short and makes each failure boundary visible.
When this pattern is a good fit
A PostgreSQL queue can be a reasonable choice when:
- PostgreSQL is already an operational dependency
- jobs are closely tied to relational state
- the workload fits within the database's tested capacity
- at-least-once processing with idempotent handlers is acceptable
- the team is willing to own retries, leases, cleanup, and monitoring
It becomes less attractive when you need very high fan-out, broker-native routing, long retention with replay, strict ordering across many consumers, independent scaling boundaries, or delivery semantics that your database design does not provide.
The practical lesson is simple: SKIP LOCKED solves the row-claiming bottleneck, not the whole queue. A reliable implementation comes from the surrounding decisions: a single claim statement, short transactions, guarded completion, explicit leases, bounded retries, idempotent effects, measured indexing, and observable queue age.